Data Pipeline2026
TenderLens
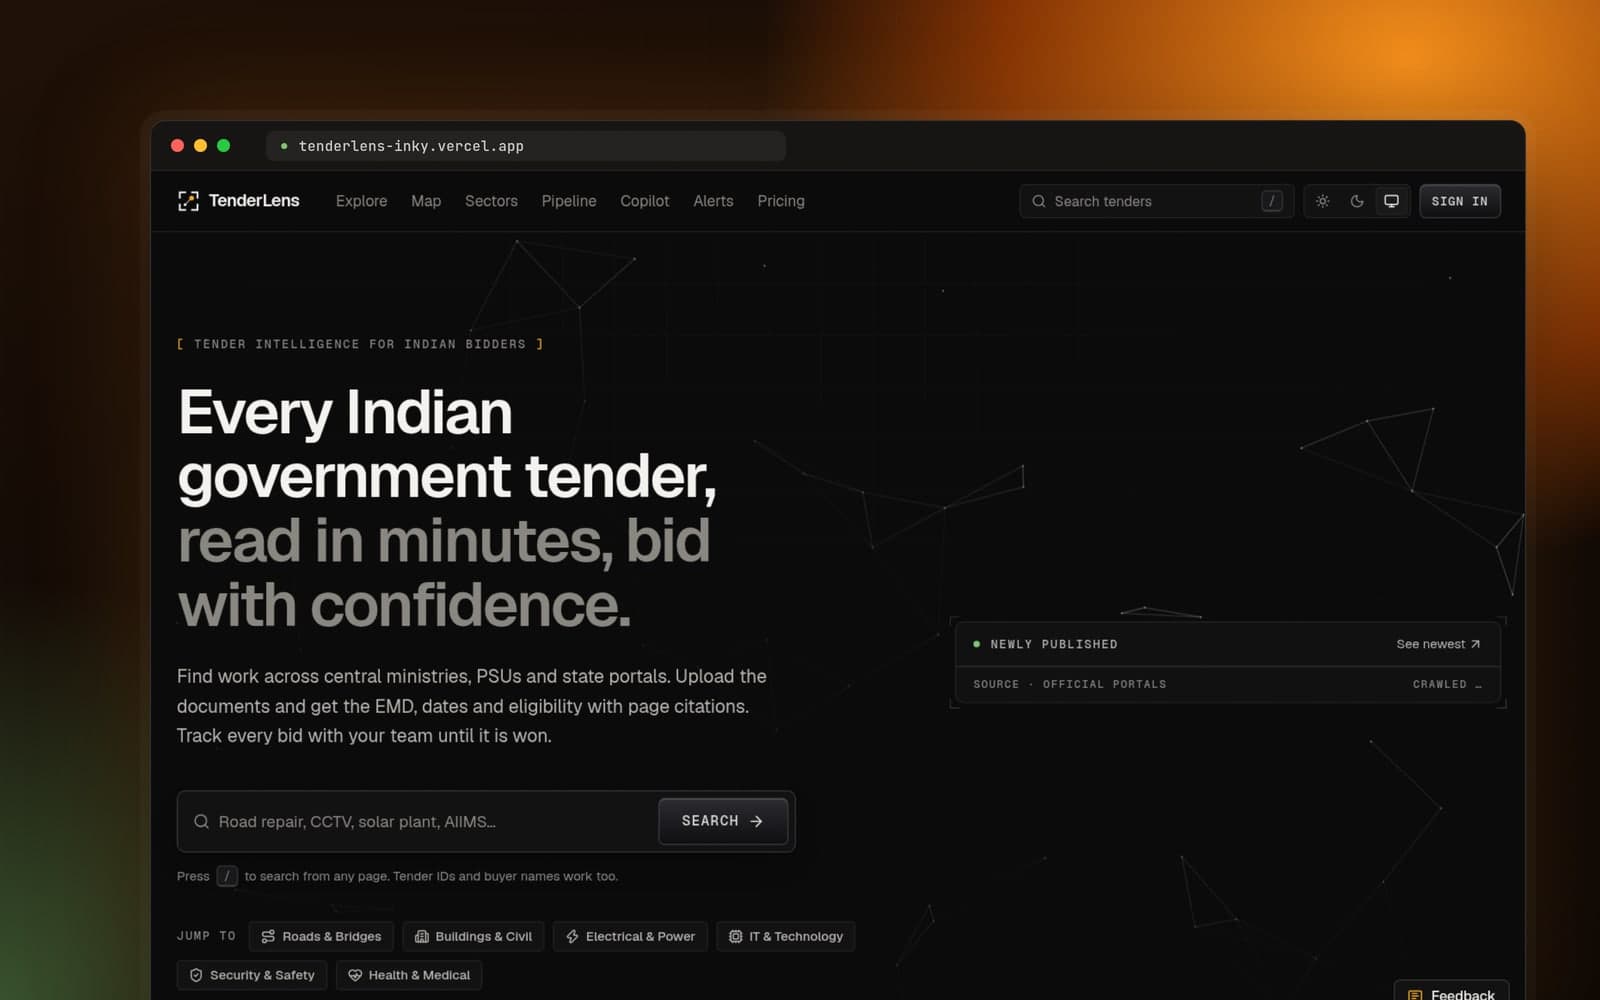
India publishes government tenders across 35 separate portals with no API. TenderLens is one searchable index of 13,107 of them, crawled hourly.
- Type
- Personal project
- Year
- 2026
- Platform
- Web
- Role
- Sole author
- Timeline
- 2026 — running
- Stack
- Python · FastAPI · PostgreSQL · Celery · Redis
The problem
Indian public procurement is genuinely public and practically unreadable. Every state, ministry and agency runs its own tender portal — around 35 of them — each with its own markup, its own pagination, its own session handling, and no API between any of them. A contractor who wants to know what is open either checks thirty-five sites by hand every morning or misses the tender.
TenderLens is the index that does not exist: one schema, one search box, 13,107 real tenders pulled from live government portals. It has run hourly and unattended since 7 October 2026.
One number belongs here rather than in a footnote, because the site's own Coverage page says it too: 35 portals sit behind one parser, and 2 of them are live on free hosting. The gap is a hosting budget, not a parsing problem. A coverage page that advertises its own hole is worth more than one that averages it away.
Build on the assumption the crawl will break
Government portals change their markup without warning, go down during business hours, and occasionally serve a different page to the same URL twice in a row. Any pipeline that treats a successful parse as the unit of work will lose data the first time one of those happens.
So the crawler stores raw before it parses. The fetched page is written to object storage with its headers and the time it was fetched, and parsing is a separate stage reading from that store. The consequence is the whole point: a parser bug is fixed by re-parsing, not by re-crawling. Re-crawling means going back to a government server that may have already rotated the listing away, and hitting it harder than politeness allows. Re-parsing costs nothing and can be done retroactively over every page ever fetched.
Writes that refuse to go backwards
Crawls overlap. A retried task, a slow worker and a fresh hourly run can all hold copies of the same tender, fetched at different times, and they do not arrive in order. The naive write — upsert on tender id — lets whichever task finishes last win, which means a stale replay can quietly overwrite newer data and nothing anywhere reports it.
Every write is instead a conditional upsert guarded on fetched_at: the update
only applies when the incoming page was fetched more recently than the row
already stored. An out-of-order replay is a no-op rather than a regression, and
the insert-versus-update distinction is read back from the write itself, so the
run can report how much of what it saw was genuinely new.
Reconcile against the source, not the broker
The failure mode that actually frightens me is not a crawl that errors. It is a crawl that returns a clean exit code having silently skipped a page.
So every run reconciles three numbers: what the portal's own index claimed was there, what was actually listed during the walk, and what was accounted for in the database afterwards. When they disagree, the run is flagged as incomplete rather than recorded as a success. That check is cheap and it is the only thing standing between an operator and a confident, wrong dashboard.
It earned itself quickly. I killed a worker mid-run with SIGKILL to see what
the queue would do, expecting Redis to redeliver the in-flight tasks to another
worker. It never did — the two tasks that were in flight were simply gone, with
no error anywhere. The next incremental crawl picked up exactly those two,
because it compares against the portal rather than against the broker's idea of
what had been delivered.
That is the whole argument, with a receipt: a queue tells you what it thinks it delivered. Only the source tells you what is actually missing.
Search on one database
The first version put Elasticsearch behind the search box, which meant a second datastore to run, to keep in sync, and to reconcile when the sync inevitably drifted. For a corpus this size that is a lot of operational surface bought with somebody else's blog post.
It came out. Search is now Postgres alone: a generated tsvector column for
full-text ranking, pg_trgm plus Levenshtein distance for fuzzy matching against
the corpus's own vocabulary rather than a generic dictionary — so a misspelled
department name corrects toward a department that actually publishes tenders —
and disjunctive facets, where each filter's counts are computed with that filter
excluded, so selecting one never makes the others look empty.
One database. No second index to keep in sync, and no class of bug where search and the record disagree about what exists.
What it does not do yet
- 33 of the 35 portals are not on a schedule. One parser covers all 35; the free tier only stretches to crawling 2 of them hourly.
- The public demo is read-only. Sign-in is not enabled, so anything behind an account is not reachable from the deployed site.
- Entity resolution across buyers is good, not solved. Agencies spell themselves several ways and the matcher still needs guards to stop distinct departments collapsing into one.
- Nothing is translated. Tenders published in regional languages are indexed as published and searched as published.