Machine Learning2026
Guard
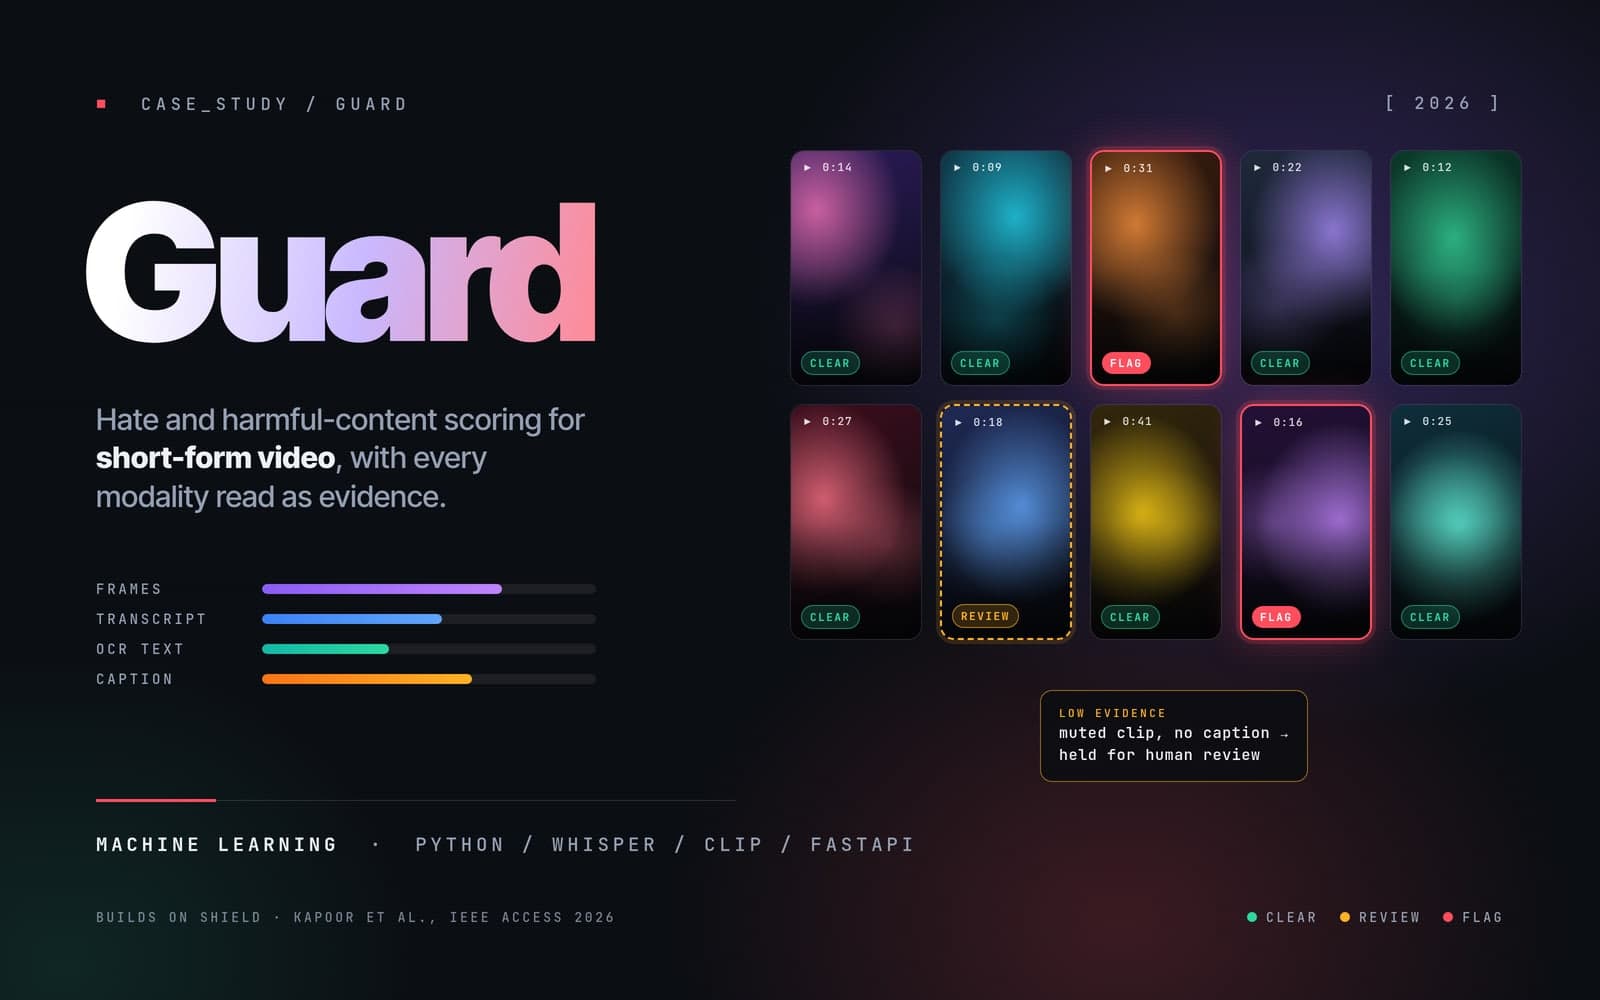
Hate and harmful-content scoring for short-form video, built on a published LLM moderation pipeline and extended with local media extraction and an async API.
- Type
- Undergraduate final-year project
- Year
- 2026
- Platform
- CLI, Streamlit app and HTTP API
- Role
- Sole committer
- Collaboration
- Builds on SHIELD (Kapoor et al., IEEE Access 2026)
- Timeline
- 2026
- Stack
- Python · PyTorch · Hugging Face Transformers · Whisper · Groq API · FastAPI · Celery · Redis · Streamlit
Starting from someone else's paper
My final-year project started from a paper I did not write. SHIELD (Kapoor et al., IEEE Access, 2026) proposes one moderation pipeline for text, images, audio and video: turn everything into text, then score that text twice, once with an LLM reading for context and once with vector similarity against category anchors. On the authors' own hand-labelled set of 6,000 files, which is not public, the LLM path reached 93.32% accuracy against 67.81% for the vector path.
Guard keeps that bet and points it at short-form video, where one clip carries its message in speech, on-screen text, caption and hashtags at once. A reworked copy of the paper's engine survives in the repository as the legacy path. The video pipeline, the scoring, the evidence model and the API are Guard's own.
Those two accuracy figures are the paper's, measured on the paper's data. Nothing in this repository reproduces them, and neither is a claim about Guard.
Take the video apart locally
SHIELD hands a video to Gemini Pro and gets a description back. Guard takes the video apart itself: frames sampled with OpenCV (or ffmpeg), a Whisper transcript, Tesseract OCR over the frames, and caption and hashtags from sidecar files. Frames also go through CLIP against prompts for hateful symbols, explicit content, violence and self-harm. Any category that clears 25 is written into the evidence as a line of text, so even the pixels become something the scorers can read. Because every piece of text has a known source, the pipeline knows what it read and, more usefully, what it could not.
Scoring is three models with different jobs, across 28 categories. A sentence-embedding model compares the text with a written description of each category, blended with keyword coverage so an explicit term is not smoothed away. An LLM on Groq, called at temperature 0, scores the same categories and carries 65% of the weight when it answers. A RoBERTa hate-speech classifier reads the text separately, and can only raise the hate score, never lower it.
The decision that mattered most here was a small one. Cosine similarity between a sentence and an unrelated category description sits around 0.1 to 0.3, and the obvious conversion, (similarity + 1) / 2, turns that noise into a score above 50. Guard maps anything under 0.14 to zero and curves the rest, and a regression test pins the mapping. A weak match should read as weak, not as half-guilty.
A silent video is not a safe video
Almost all of Guard's evidence is what a clip says and shows as text. Take that away (a muted clip, a missing Whisper install, no caption file) and the scorers have almost nothing to read. Almost nothing scores low, and a naive pipeline reports low as safe.
Each result records which of the four text sources were present and which extractors were installed. With no primary text, the original pipeline marks the result as insufficient evidence unless its trained classifier is independently confident, pins the safety score to the midpoint and refuses to call the video safe to watch. Regression tests hold that rule in place. A video that fails to process comes back as REVIEW rather than dropping out of the report.
When Guard cannot see enough to judge, the right output is "a person should look at this", not a confident number. The paper agrees: decisions with real consequences belong to human reviewers.
The rebuilt pipeline, the one the API runs for video, holds that line less well than it looks. Its confidence score gives up to 45 points for the amount of text and up to 65 for installed extractors, engines that ran and clip length. A 30-second clip with nothing to read, on a fully configured machine, comes to about 64: "fallback", not "insufficient". The REVIEW floor never engages, and a low score can still come back SAFE. The rewrite kept the rule's vocabulary but measures tooling more than evidence.
Accepting a video is not judging it
The paper's proposed architecture runs the pipeline between the API request and the API response. That works for a sentence, not for a video that has to be transcribed, read and scored by three models.
Guard's request path is short. FastAPI validates the upload, writes a job row to SQLite, stores the file and returns. Celery workers pull from a separate Redis queue per modality, so a backlog of video does not hold up text. Tasks are acknowledged late and go back on the queue if a worker dies. An idempotency key backed by a unique index means a retried submission gets the same job back, not a second one. Results are polled or pushed by webhook.
Accepting a video and judging it are separate jobs, and only the first happens inside the request.
One flaw belongs here. A circuit breaker switches to keyword scoring after three failures, but the LLM scorer catches its own network errors and quietly falls back to embedding-only scores. A Groq outage never trips the breaker: every job still makes the call, then degrades, and the only trace is a flag in that job's result.
What it does not do
- There is no measured accuracy for Guard in this repository.
eval.pyscores predictions against a labelled hate / non-hate video folder and prints them beside SHIELD's published figures, but no output and no dataset is committed. Its own note warns that binary labels make the regression metrics a 0-or-100 proxy for the paper's human severity scores. - The trained classifier cannot hear the video. The optional phase-1 model is a small MLP over duration, resolution, file size, audio presence and mean frame colour. It can learn a dataset's quirks, not what anyone said, and its best epoch and threshold are both picked on the validation split.
- Most weights are set by hand. The risk blend, modality weights, regional multipliers and evasion phrase lists are constants. The config asks for a learned fusion model, but none ships and nothing here trains one.
- Irony counts against you. The rebuilt pipeline counts words like "ironic" and "joking" as signs of evasion, so a clip that really is a joke scores slightly riskier. The paper reports the mirror image: its LLM's false positives clustered in emotional and metaphorical language.
- The timeline view is approximate. Whisper's segment times are discarded and the transcript is split evenly across five-second windows, as if speech were spread evenly through the clip.